On 14 September 2026, we released Klang Dialects, an open dataset and benchmark for Swedish speech recognition. The recordings came from Knäck Klang, where participants read three sentences in their own dialect. The harder Klang found it to transcribe their speech, the more points they earned.
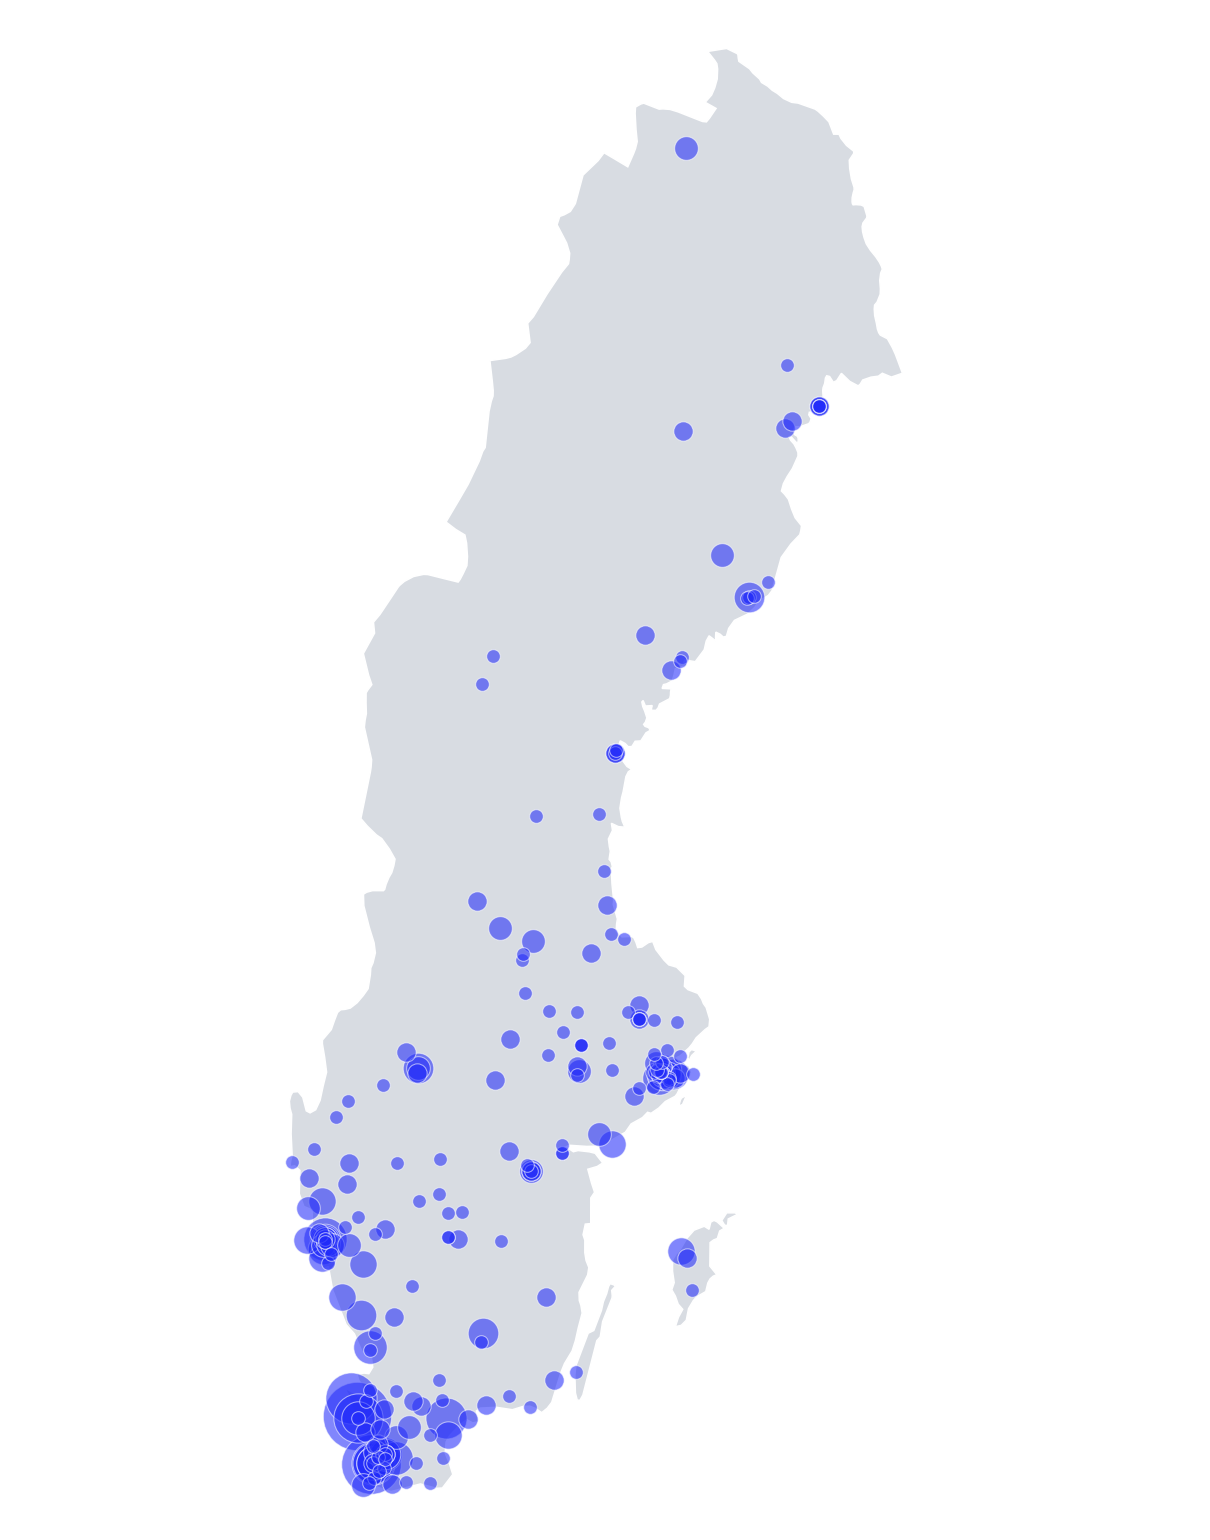
Swedish dialects are underrepresented in commonly used speech recognition benchmarks. Klang Dialects lets researchers and developers explore how the technology handles different ways of speaking Swedish. Contributions come from across the country, with the most recordings from southern Sweden.
The sv-clean version contains 1,804 recordings with quality-checked reference transcripts. Our research team manually reviewed around 1,000 recordings to make sure the text matches what was actually said. The dataset is freely available on Hugging Face, along with documentation on how to use it.
Get the dataset on Hugging Face