Hugging Face
Run on your own infrastructure.
Download the weights, adapt the model and build on it. You choose the hardware and where your audio is processed.
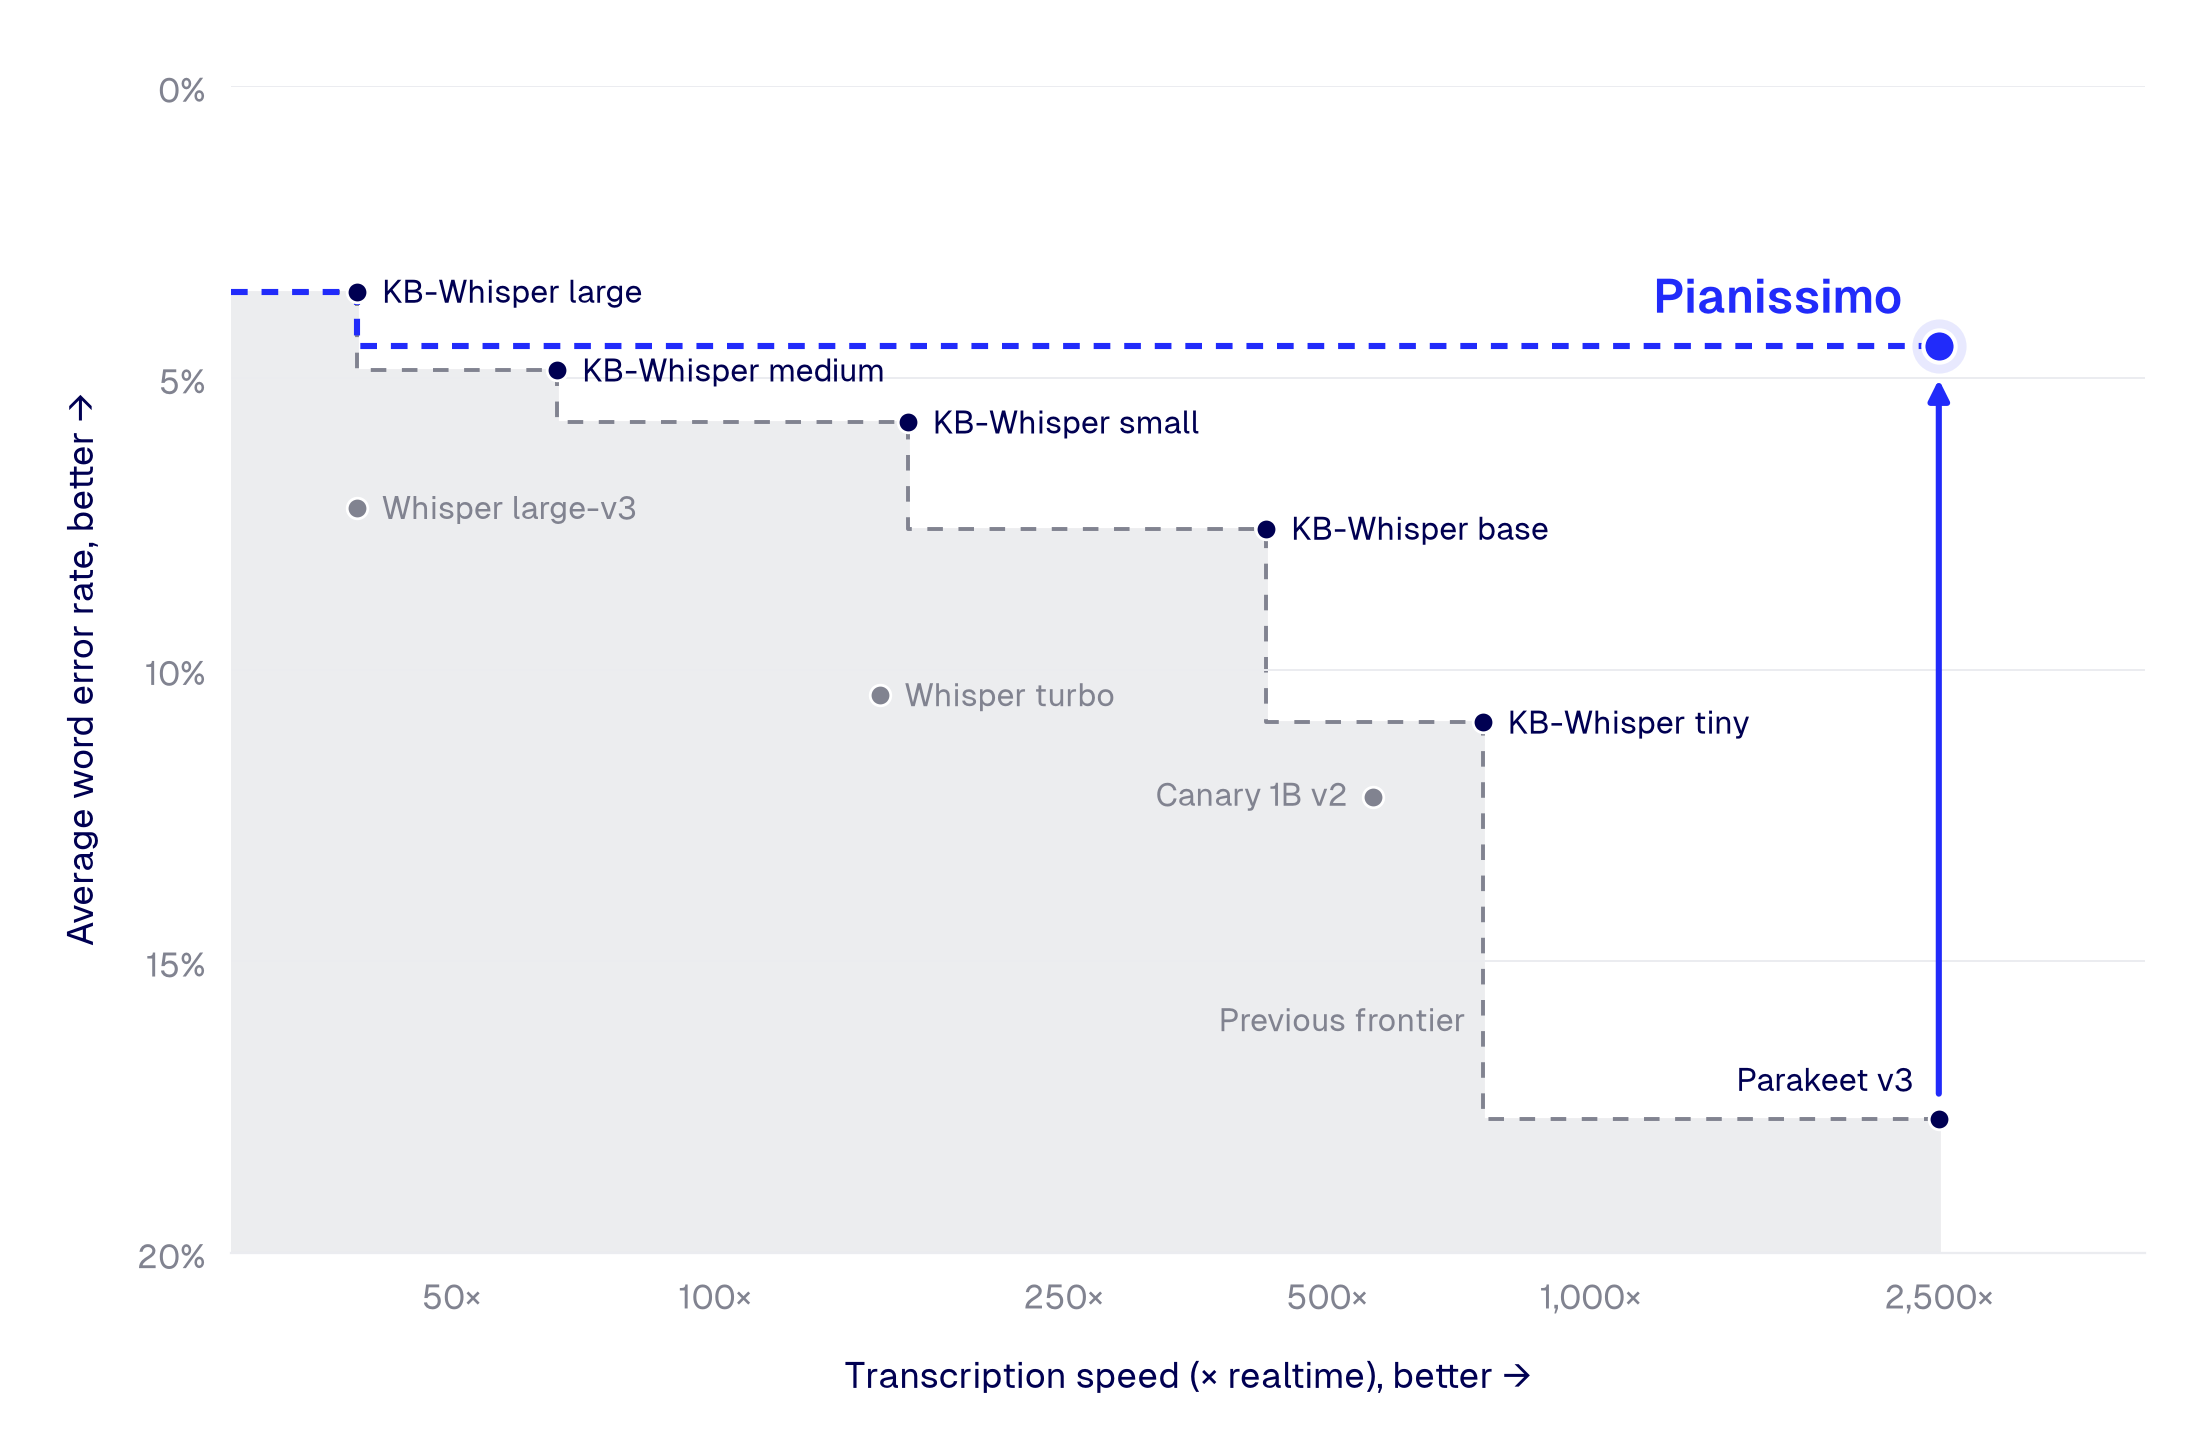
Klang Pianissimo is an open speech-to-text model for Swedish, fine-tuned from NVIDIA’s Parakeet v3. It achieves a 4.5% word error rate on Common Voice and transcribes an hour of audio in one second.
Try transcribing Selma Lagerlöf, or try the model on your own audio.
Connecting to the model…
Drop a file onto the player. Up to 90 minutes. Audio is sent to Klang for transcription.
Pianissimo achieves word error rates comparable to KB-Whisper large, at 64 times the speed.
Faster to the right. Fewer errors toward the top.
Scroll sideways to see the full chart.
to transcribe an hour of audio
Pianissimo is an open model, built for sovereignty. Run it on your own infrastructure or use it through our partner Berget AI. You choose where your audio is processed.
European AI needs models that others can build on. Open weights let you run Pianissimo locally, choose a European provider and switch as your needs change.
Built something with Pianissimo? Tell us about it at [email protected].
Klang makes your conversations searchable and usable - with transcriptions, summaries, and insights. Built in Europe, with trust at its core.